Showing posts with label semantic web. Show all posts

Sunday, March 28, 2010

Health Data, Self-serve, Visualization, Semantic Analysis and Collective Intelligence

Notes from the Biomedical Data Mining Camp Session led by Dr. Irene Gabashvili and other health-related discussions at Data Mining Camp and Transparency Camp 2010.

The title for the session was "Biomedical Data Mining: Successes, Failures, and Challenges" (streamed online from Fireside C).
The topic stemmed from the similarly named last year's session - Biomedical Data Mining: Dimensionality, Noise, Applications - now split into several discussions including Bioinformatics & Genome Sequencing organized by Raymond McCauley, Dimensionality Reduction moderated by Luca Rigazio (HLDA / HDA; LDPP; Core Vector Machines; Sparse Proj SQ; Random Projection and Feature Selection).

Main sub-topics of the biomedical session were:
  • Reality Mining
  • Visualization
  • Imaging
  • Signal Processing
Reality mining is expected to improve public health and medicine. It was named as one of "10 emerging technologies that could change the world". This is not only about mining data pertaining to social behavior - although social factors do impact well-being and social data provides valuable health predictors. It's also about health data collected in real and near real time. Audience asked about ways to collect health data and their limitations. Some of the questions reflected earlier Q&A with the Data Mining Camp expert panel , especially Dr. Michael Walker, author of numerous FDA and CLIA-approved products to diagnose and treat disease. He commented on the need to have tools well beyond the data available to take cell samples every two minutes instead of laboratory testing every few months - in order to allow cellular simulations and obtain parameters for differential equations. Sampling frequencies don't come close to allow this kind of modeling. Irene Gabashvili agreed that first-principles cellular modeling for predicting health won't be possible (although there are engineers that believe a platform for real-time in-vivo measurements of most cells can be developed). Yet, good predictors could be and will be developed - based on sensors measuring macro-level observations and missing value estimators. Genetic information is not enough, we need to capture environmental risk factors. How can we separate genes and environment?, asked one of the participants. Aurametrix' initial focus is on chemicals in our food - and even though some may argue that our taste and satiety mechanisms are dictated by genes, food analytics provides insights into non-genetic components of our health. Other questions were on the time line for body sensor networks and data growth. Jeffrey Nick of EMC estimates that personal sensor data will balloon from 10% of all stored information to 90% within the next decade. Irene Gabashvili thinks that this will happen rather sooner than later, perhaps in the next two years.

Another interesting aspect of reality mining is crowdsourcing or collective intelligence - in order to get useful information from all the data (temporospatial location, GPS, activity, food, symptoms, behavior, communication content, proximity sensing), we need to analyze it not only on individual but also group level. We need to share more, without sacrificing privacy and security. Collective contributions can be reliable - Shamod Lacoui's answer to this is in selecting those who contribute, restricting inputs to domain. It would help to “filter out the dross”, while “saving the best”. It is needed to suppress noise, to infer intelligence from the collection of facts, clicks, steps, whatever one can contribute. This resonates with discussions at the Transparency Camp - one of the useful tools is SwiftRiver - free, open source software platform to validate and filter news. Swift relies on Natural Language Processing, Machine Learning and Veracity Algorithms to track and verify the accuracy of reports and suppress noise (like duplicate content, irrelevant cross-chatter and inaccuracies). Transparency Camp also posed a question on whether there is a need for an FDA-like institution to ensure information safety and healthy information consumption.

Self-serve was a topic of a smaller Data Mining Camp Session. Even though it was aimed at sales reps that need to go beyond Excel spreadsheets to mine private data of their interest, self-service is currently the only option for health care consumers. People need to analyze everyday life for health implications. They need better tools to not focus on metrics that are easy to collect instead of metrics we need to collect.

In order to mine high-dimensional health space, many disparate types of data should be mashed and validated, gaps should be bridged and structured metadata added to data. Randy Kerber talked about data formats and approaches to make it happen. Semantic web discussions involved NoSQL experts that mentioned limitations of gaining popularity technologies such as MongoDB, Cassandra and HBase. Another relevant session - on cloud computing - discussed its (sometimes over-rated ?) performance and Hadoop technologies.

Visualization techniques provide one of the most effective methods of extracting knowledge from health data. Remember who invented the pie chart? That's right, it was Florence Nightingale, a nurse who needed a way to better represent her data. one of the most famous examples of visualizing epidemiological data was Dr. John Snow's map of deaths from a cholera outbreak in London, Many other techniques and software tools exist, but maps remain popular - especially google maps API. One of popular tools for epidemiological data is Google Maps API. For example, it embeds Google Maps into healthmap.org with JavaScript.

One of the participants of Biomedical Session developed kidsdata.org (@kidsdata on twitter). It provides insights into geospatial autism statistics and visualizes trends and other useful health-related information.

Another way to display geospatial data is Dynamic Choropleth Maps. Complex networks can be also explored with alluvial diagrams and other approaches. More visualization techniques and tools can be applied to health data - to look at the data in new ways and gain useful insights.

Some of the questions from the audience were on the availability of data. Sources discussed included CDC (see, for example, NHANES laboratory files; eHealth metrics) and Entrez Life Sciences databases.

Signal Detection and Signal Processing for Mining Information was another discussion topic.
Questions were on data mining versus simple tracking and signal monitoring. It was agreed that data mining is the key to health management. Cardionet, body sensors (see posts on teletracking, M-health, Telemedicine: part 1; Telemedicine: part 2; Health 2.0 Software tools, Devices to keep you healthy), SNP detection, telemedicine applications, random and rare electrocardiographic events and other applications were also discussed.


See other materials from Data mining Camp 2010:


Reblog this post [with Zemanta]

Tuesday, March 2, 2010

Organizing the World's information

"My guess is (it will be) about 300 years until computers are as good as, say, your local reference library in doing search,"says Google's first employee and director of technology Craig Silverstein. "But we can make slow and steady progress, and maybe one day we'll get there." (Inside the Wide World of Google CBS News, March 28, 2004). According to CEO Eric Schmidt, people care a lot about information and the possibilities of the unfolding revolution in technology are greater than many of them even realize: “Imagine the scale of the kinds of questions you could ask that you could not ask before.”

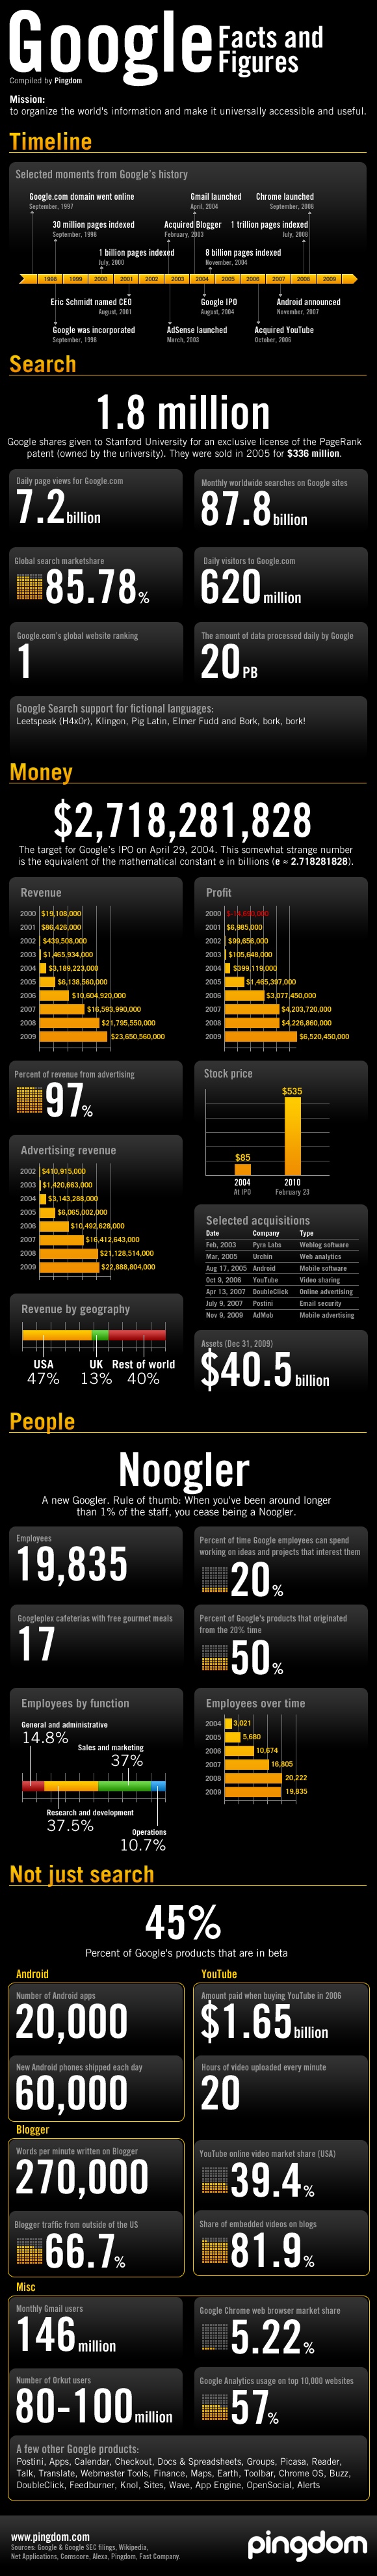
The figure is a great compilation of key Google Facts by PingDom. Among the key technical facts not shown here are far-reaching inventions such as Programmable Search Engine (PSE, see patent application) based on the BigTable database (See Research Publication about it in PDF format) and other systems that could help it become more semantic.

The distributed storage system for managing structured data called Bigtable resembles a database sharing implementation strategies with parallel and main-memory databases. Instead of a full relational data model it uses a simple data model with data indexed using row and column names that can be arbitrary strings. A Bigtable is a sparse, distributed, persistent multidimensional sorted map. The map is indexed by a row key, column key, and a timestamp; each value in the map is an uninterpreted array of bytes, although clients often serialize various forms of structured and semi-structured data into these strings, controlling it through careful choices in their schemas.

PSE and other integration technologies may be providing a higher level of semantic analysis.
These techniques could figure out the meaning of content and “fill in the blanks” when an item of information is ambiguous or missing. The idea is to enrich an information object with additional tags so that queries about lineage (where something came from) and likelihood of accuracy (the “correctness” of an information element) can be used to generate a result.

Another new concept is a probabilistic mediated schema automatically created from the data sources. Semantic mappings between the schemas of the data sources are mediated by schemas with probabilities attached to each - to model uncertainty at its core. A deterministic mediated schema created from the probabilistic ones will be exposed to the user who could use the terminology of this mediated schema to interact with the system.

The Semantic Web is emerging to help us get the most out of the world's information. Many interesting applications are already here. Some of them already acquired by major search players - Bing, for example, is based on semantic technology from Powerset that Microsoft purchased in 2008. This blog article is only about one of the players organizing the world's information. Stay tuned for more.


Reblog this post [with Zemanta]

Tuesday, January 5, 2010

Semantic Web

An updated SVG of the FOAF logo. I created the...Image via Wikipedia

The semantic web promises to define the meaning of its content (semantics) making computer programs able to perform all the tedious work of searching, comparing and combining bits and pieces of information - all the tasks we have to do by ourselves in order to find answers to complex questions.

Attempts to make this possible includes languages: Resource Description Framework (RDF), Web Ontology Language (OWL), and Extensible Markup Language (XML); data interchange formats (e.g. RDF/XML, N3, Turtle, N-Triples), and notations such as RDF Schema (RDFS). Some believe that even simpler unambiguous formats will be part of the semantic web.

An early example of a semantic web application, FOAF (an acronym of Friend of a friend) expressed using RDF and OWL is a descriptive vocabulary, an ontology describing people, their activities, and relations to each other. Check, for example, semantictweet.com that allows to turn Twitter accounts into FOAF profiles.

Simpler components of semantic web include meta-tags - an extension of metadata in the form of tags used to describe Web pages' content in the early days of web design. This could be labels with keywords, name of the page author, description or metadata representing sets of facts. Ontologies are often used to generate metadata and mapping between vocabularies.
Zemanta system semantically filters content of the page to automatically tag it or suggest other relevant content. Semantic standards like Common Tag - developed jointly by Zemanta, Metaweb, and Yahoo! - add semantic meaning to tags expressed using RDFa, making Web content more discoverable and decentralized. With Common Tag, content is tagged with unique, well-defined concepts - everything jaguar the animal is tagged with one concept for jaguar the animal vs. the car.

Ontologies defined as "an explicit specification of a conceptualization" are about the kind of things existing in the domain and their relations to each other. There could be no perfect scheme, however. In working classification systems, success is not "Did we get the ideal arrangement?" but rather "How close did we come, and on what measures?" There are no fixed shelves and perfect arrangements. It would not hurt to rearrange things from time to time, add a few secondary links and subdirectories. "This book is mainly about the Balkans, but it's also about art, or it's mainly about art, but it's also about the Balkans." The classification can not be perfect - except very small and specialized domains, stable entities, clear edges, authoritative sources and a lot of money to support the authoritarian system. This will never work for the Web - with many uncoordinated users that don't think alike and are naive classifiers.

Web users have very different tagging strategies too - but all together they are creating value for one another, by connecting similar tags.

Some of most often mentioned examples of semantic web application include Freebase - an open database where anyone can perform complicated queries. It is like a structured version of Wikipedia, combining the advantages of free text and relational databases. It's qualified users can not only add the content but also change the structure itself modifying the definitions of existing types. With many qualified users both the content and structure will evolve over time.

Even though some sources claim that Freebase is built around an exhaustive ontology, it's more like a collection of ontologies or rather tags. Unlike the W3C approach to the semantic web, which starts with controlled ontologies, Metaweb adopts a folksonomy approach, in which people can add new categories (much like tags), in a messy sprawl of potentially overlapping assertions.

See more on the State of Linked Data in 2010:
From the Semantic Web to the Web of Data: ten years of linking up

An example of a semantic data storage tool able to analyze networks and events in large volumes of structured and unstructured data is AllegroGraph. this RDF graph database can be, for example, used for GeoSpatial and Temporal Reasoning performing complicated queries against news articles scraped from Google

NYCSW GeoSpatial, Temporal Reasoning with AllegroGraph from Morton Swimmer on Vimeo.


Reblog this post [with Zemanta]

Sunday, May 31, 2009

From "Dr. Knows Best" to Health 4.0

The human brain provides inspiration for artif...Image via Wikipedia
Mirrored from Aurametrix Blog
What is Health 4.0? To answer this question, let’s take a look at the evolution of World Wide Web.
1st Generation Web, a.k.a internet before the bursting of the dot-com bubble, was a dial-up, 50K bandwidth, built around fixed content, with static pages and framesets providing one-way web of information.
Web 2.0 is usually associated with interactive information sharing, user generated content and the rebound of the Internet after dot com crash. It's "an average 1 megabit of bandwidth Web 3.0 will be 10 megabits of bandwidth all the time, which will be the full video Web, and that will feel like Web 3.0” says Netflix’ Reed Hastings . Everybody has a slightly different vision of generations 2.0, 3.0 and beyond.What are they? In a nutshell:
Web 1.0 “read-only”
Web 2.0 “read-write” (blogs, RSS feeds, tagging)
Web 3.0 “read-write-execute” (small apps with data in the cloud- as envisioned by google; a true communal media – citing yahoo; )
Web 4.0 when all of the above come together to form the learning self-aware Web, the era of artificial intelligence
According to by Tim O'Reilly', in the Web Squared everything and everyone in the world casts an "information shadow," an aura of data which, when captured and processed intelligently, offers extraordinary opportunity and mind bending implications. Web 3.0 will be some sort of virtual reality. If 1990-2004 was the match being struck; 2005-2009 was the fuse; and 2010 will be the explosion.
Web 1.0
Web 2.0
DoubleClick --> Google AdSense
Ofoto --> Flickr
Akamai --> BitTorrent
mp3.com --> Napster
Britannica Online --> Wikipedia
personal websites --> blogging
evite --> upcoming.org and EVDB
domain name speculation --> search engine optimization
page views --> cost per click
screen scraping --> web services
publishing --> participation
content management systems --> wikis
directories (taxonomy) --> tagging ("folksonomy")
stickiness --> syndication

We are now at the fork of Web 2.0 and Web 3.0, focusing on usability for humans and on internet architectures for machines. Some call web 3.0 a 3D game-environment web or a semantic web. Semantic Web was envisioned byTim Berners-Lee as a universal medium for data, information, and knowledge exchange easily understood by computers. Semantic technologies are already out there, for example, TrueKnowledge, Zemanta, newssift, wolframalpha, nextbio…
Web 3.0 is a truly personalized web, a customized information delivery system tuned to your every want and need, whenever and wherever you are.
Analogous to the Generations of the Web, everybody is talking about Entrepreuneur 2.0, Women 2.0, DNA Sequencing Technologies 3.0… Business models for health care evolved from solution shops to facilitated networks, transforming the organization of health care delivery.
So, what is Health 4.0? According to this blog:
Health 1.0 = content
Health 2.0 = content + community
Health 3.0 = content + community + consumer-centric commerce
Health 4.0 = content + community + working commerce models + coherence
If that’s all it takes, Aurametrix is already building Health 4.0 technologies.
Health 2.0 is participatory medicine, says Web 2.0 evangelist Mark Scrimshire: Health 2.0 = (Me + MD)Us , where our relationship with medical doctors is enhanced by the community - all of us. Wikipedia definition of Health 2.0 (adopted from Hughes B, Joshi I, and Wareham J paper "Health 2.0 and Medicine 2.0: Tensions and Controversies in the Field" published in Journal of Medical Internet Research) is the use of a specific set of Web tools (such as blogs, tagging, search, wikis, etc) by actors in health care including doctors, patients, and scientists, using principles of open source and generation of content by users, and the power of networks in order to personalize health care, collaborate, and promote health education.
CHW Health blog gives the following definitions:
Health 1.0 Disenfranchised patients, a ”Dr. Knows Best” approach.
Health 2.0 The empowered consumer
Health 3.0. Personal responsibility becomes part of the social contract we all have with one another. Not only will consumers be given the tools and information they need to make better choices — they’ll be expected to do so. And there will be consequences for not doing so.
But consumer owned health care isn’t quite here yet, even though number of US Health 2.0 consumers is at 60 million. 10 million adults use their cell phones and PDA/smartphones to look up health and medical information, and “a growing number of patients are rating prescription drugs and treatments on sites like iGuard.org, DailyStrength.org, PatientsLikeMe, and WebMD.” Check out the top health web apps, Health 2.0 apps, the trends to watch in health 2.0, the latest industry stats and Health 2.0 updates by ReadWriteWeb.
We see Health 3.0 as truly personalized and highly coordinated health management services, customized diagnostics and expert advice... Just wait and see. You'll like it!
So, Long Live Health 2.0! Welcome Health 3.0! And let’s start thinking about generation 4.
Reblog this post [with Zemanta]
blockquote { margin:1em 20px; background: #dfdfdf; padding: 8px 8px 8px 8px; font-style: italic; }